Built for AI that thinks and acts
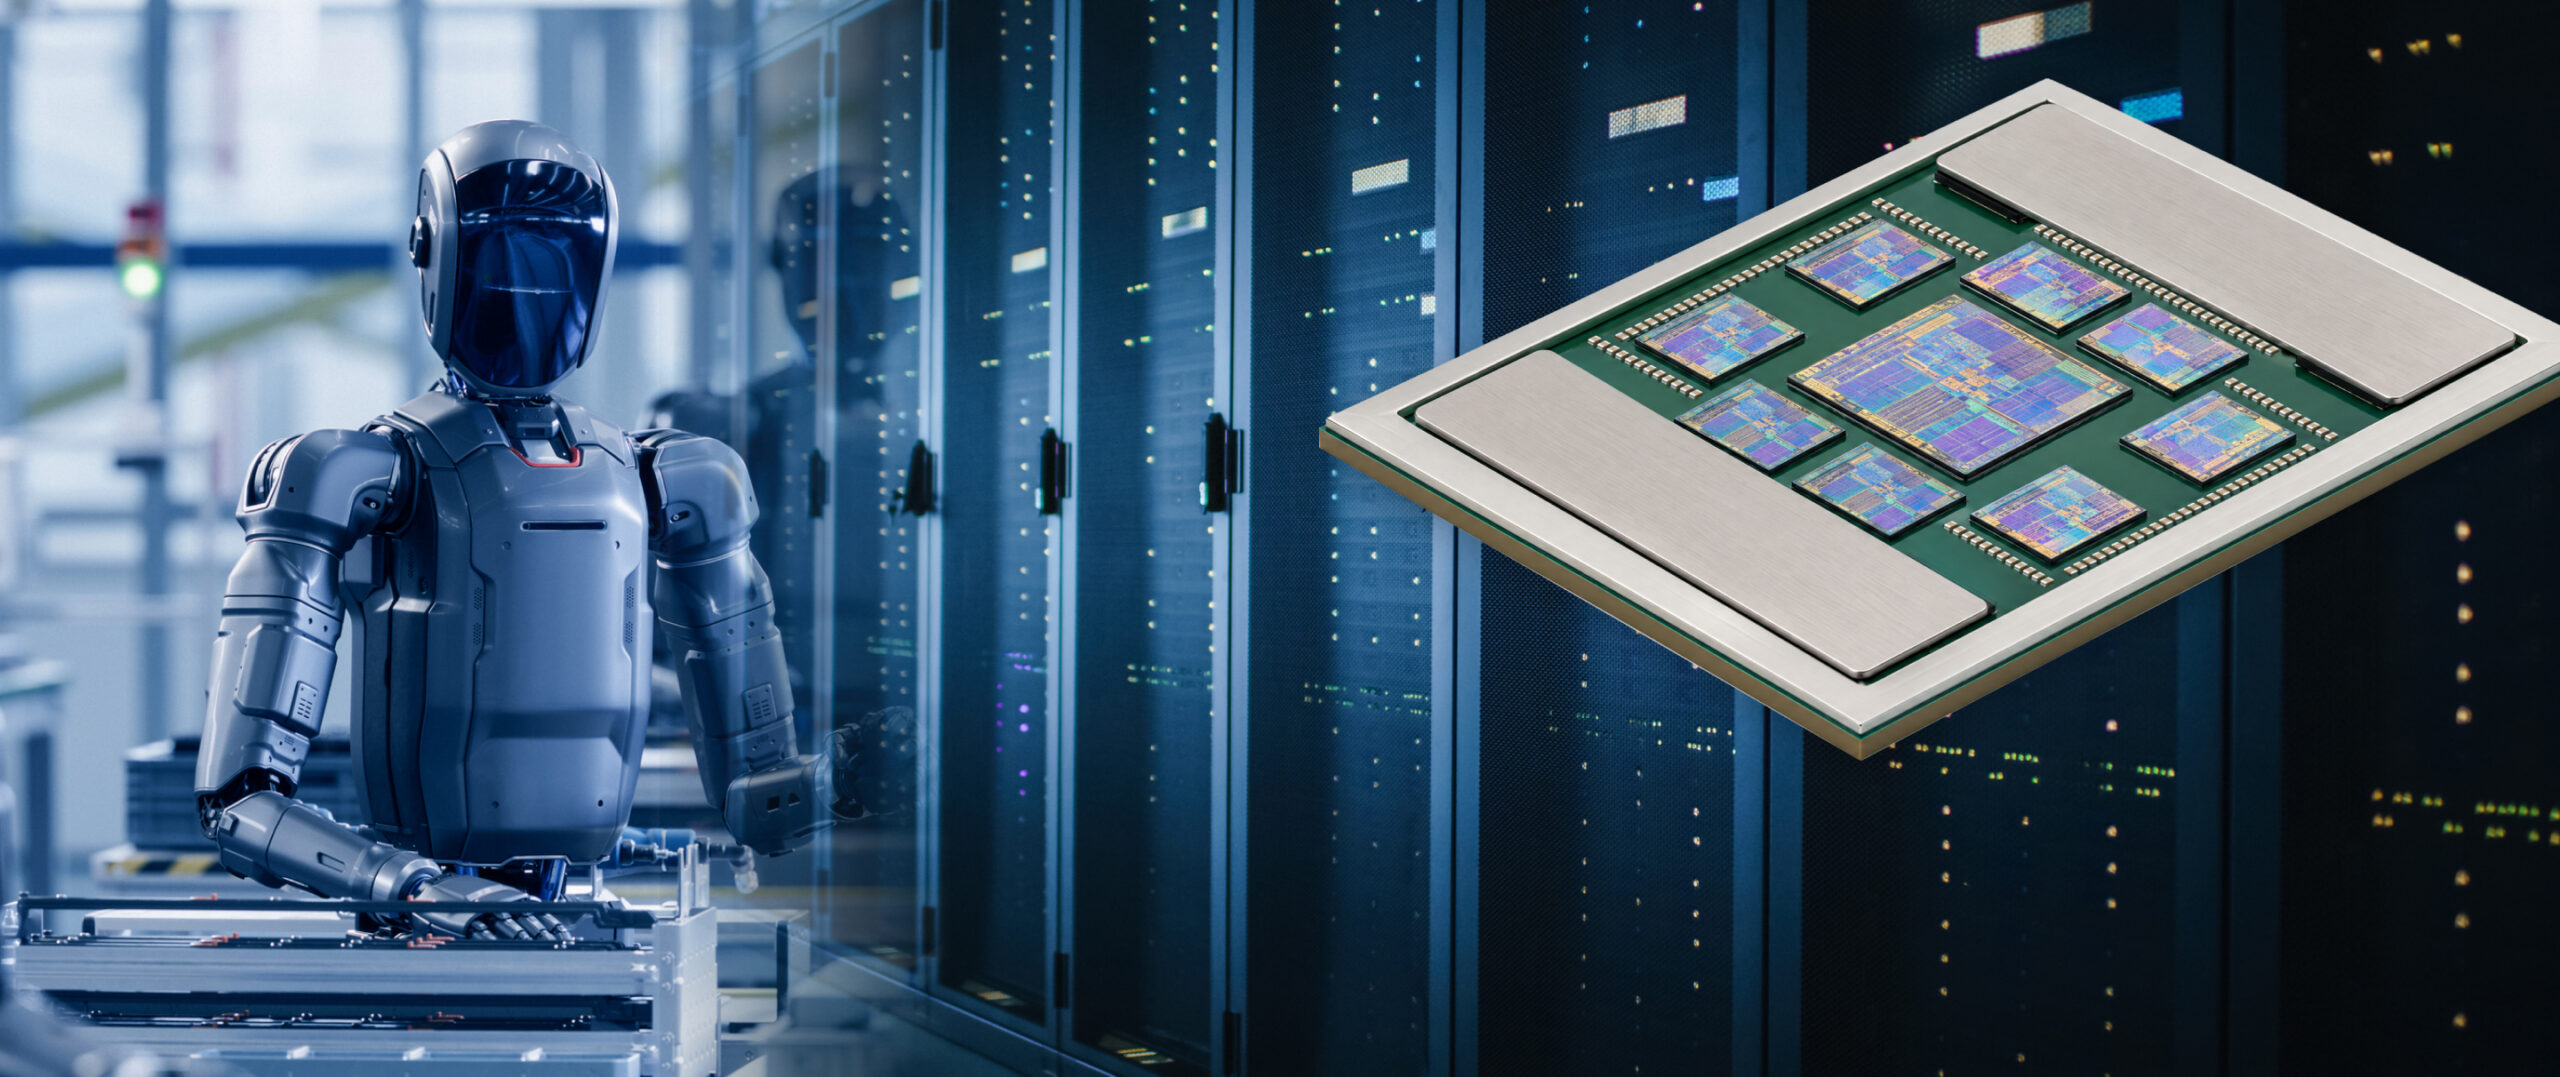
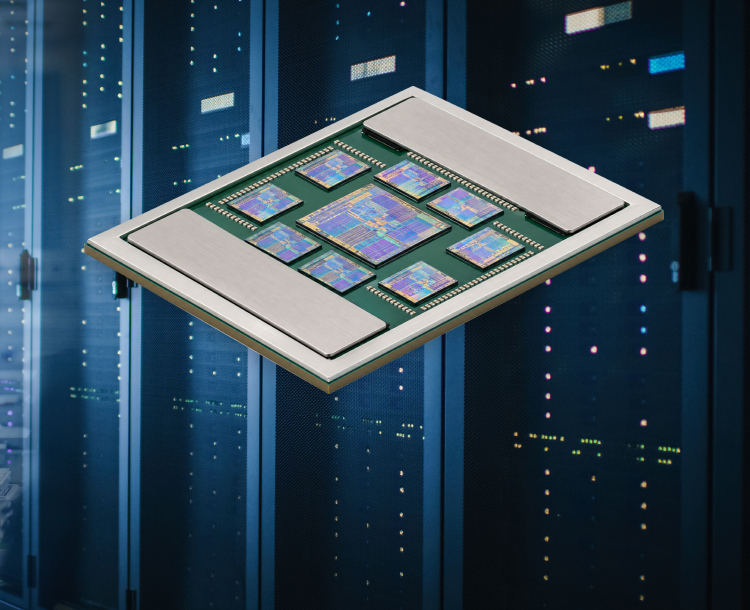
Tsavorite’s Omni Processing Unit brings CPU and AI cores into one shared-memory architecture that couples reasoning with execution, from intelligent devices to datacenters.
Contact us
Composable by design.
Efficient by architecture.
Unified by software.
With unified memory, composable chiplets and the breakthrough MultiPlexus fabric our architecture provides unmatched computational efficiency while enabling AI models to operate at the highest performance.

Performance that improves with scale
Unlike GPUs where utilization drops as clusters grow, the Omni Processing Unit delivers greater performance density with the larger the system gets. Scale becomes a feature, not a tradeoff.

One runtime, everywhere
Tsavorite Agentic Operating Stack (TAOS) provides developers a unified, CUDA-compatible, PyTorch-first software stack. It allows developers to run any model, or workflow – training, inference, or fine-tuning – without code changes or framework lock-in.

10x increase in arithmetic intensity
The MultiPlexus fabric keeps data closer to compute, reducing redundant transfers and increasing arithmetic intensity tenfold.
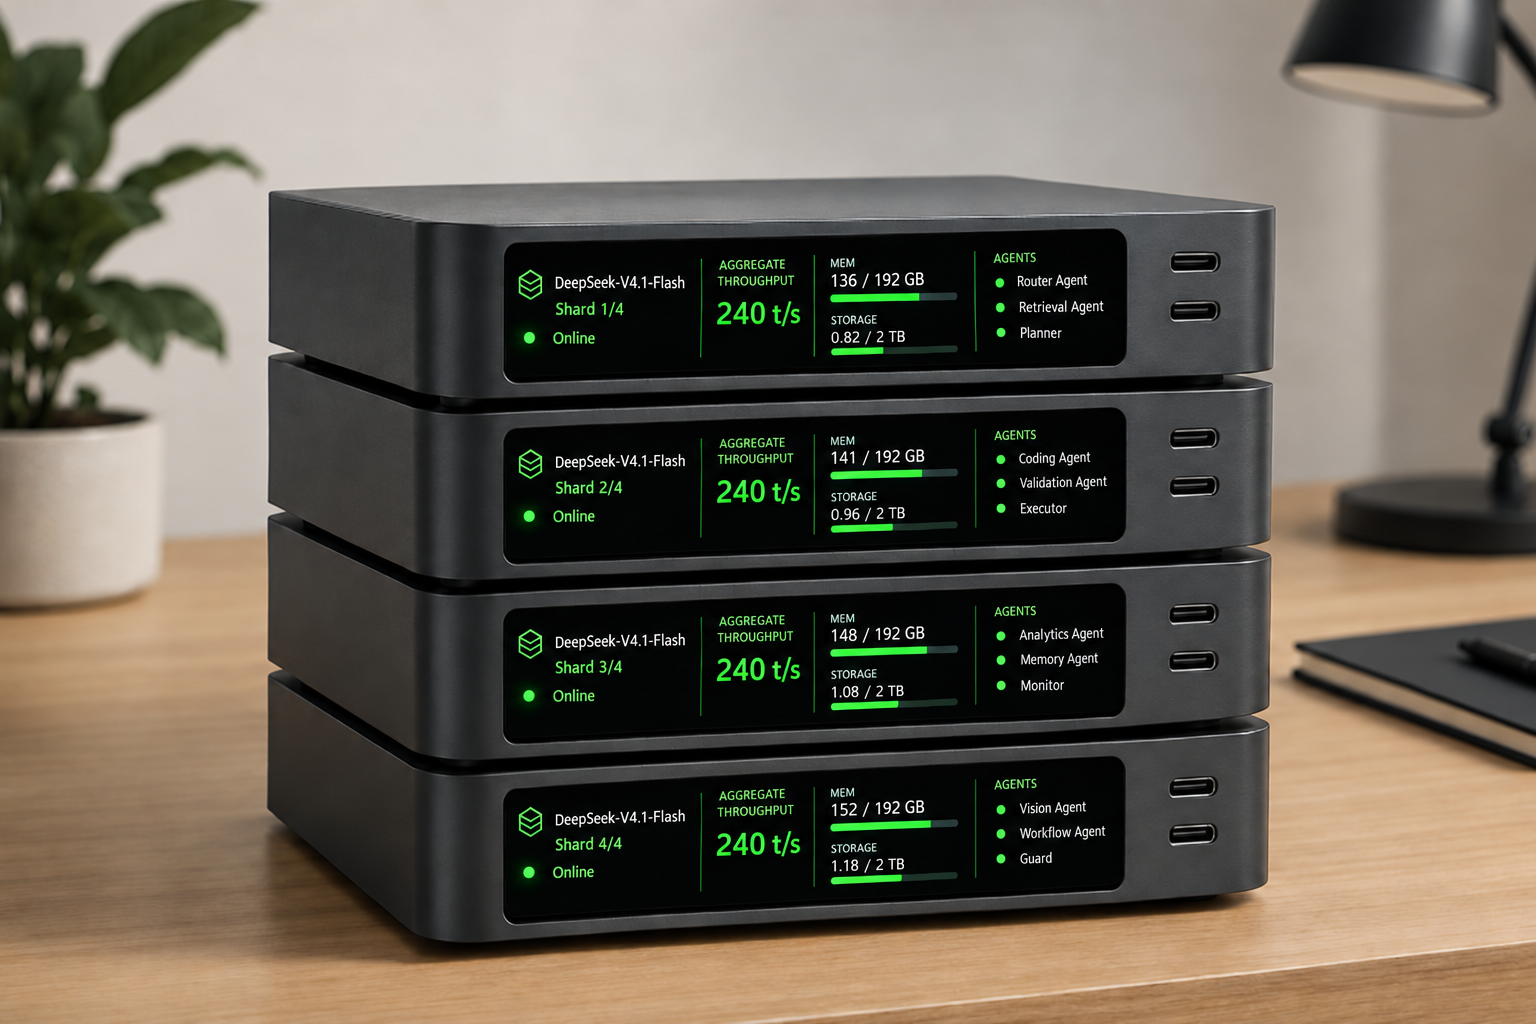
All-in-one solution bringing generative AI to the Edge
Our innovative approach breaks through traditional computing limitations. We engineer solutions that transform complex computational challenges into elegant, high-performance workflows.
Technology
The compute engine of the OPU: thousands of efficient cores, paired with Arm Neoverse, running any AI/ML model with built-in security and hardware-managed scheduling.
AI OmniCore
The AI OmniCore is the compute engine at the heart of the Omni Processing Unit. It runs any AI/ML model across training, fine-tuning, and inference. Flexible matrix shapes, multiple contexts per core, and hardware-managed resource arbitration keep utilization high, while confidential compute and virtualization are built into the core itself.
Learn more
MultiPlexus
MultiPlexus is the coherent fabric that makes the OPU composable. One fabric spans every scale: a high-performance network on chip with distributed caches, extended over UCIe to connect every chiplet in a package, over SerDes to connect every package in a system, and across systems and racks to form unified memory pods. As the fabric scales up, arithmetic intensity rises as much as 10x and AI compute utilization climbs with it.
Learn more
One architecture for every scale of intelligence
Whether enabling Physical AI at the edge, Agentic AI in enterprise systems, or foundation model training in the cloud, the Omni Processing Unit delivers one consistent architecture: composable, efficient, and ready for the next generation of intelligent infrastructure.
At the Edge and On-Prem
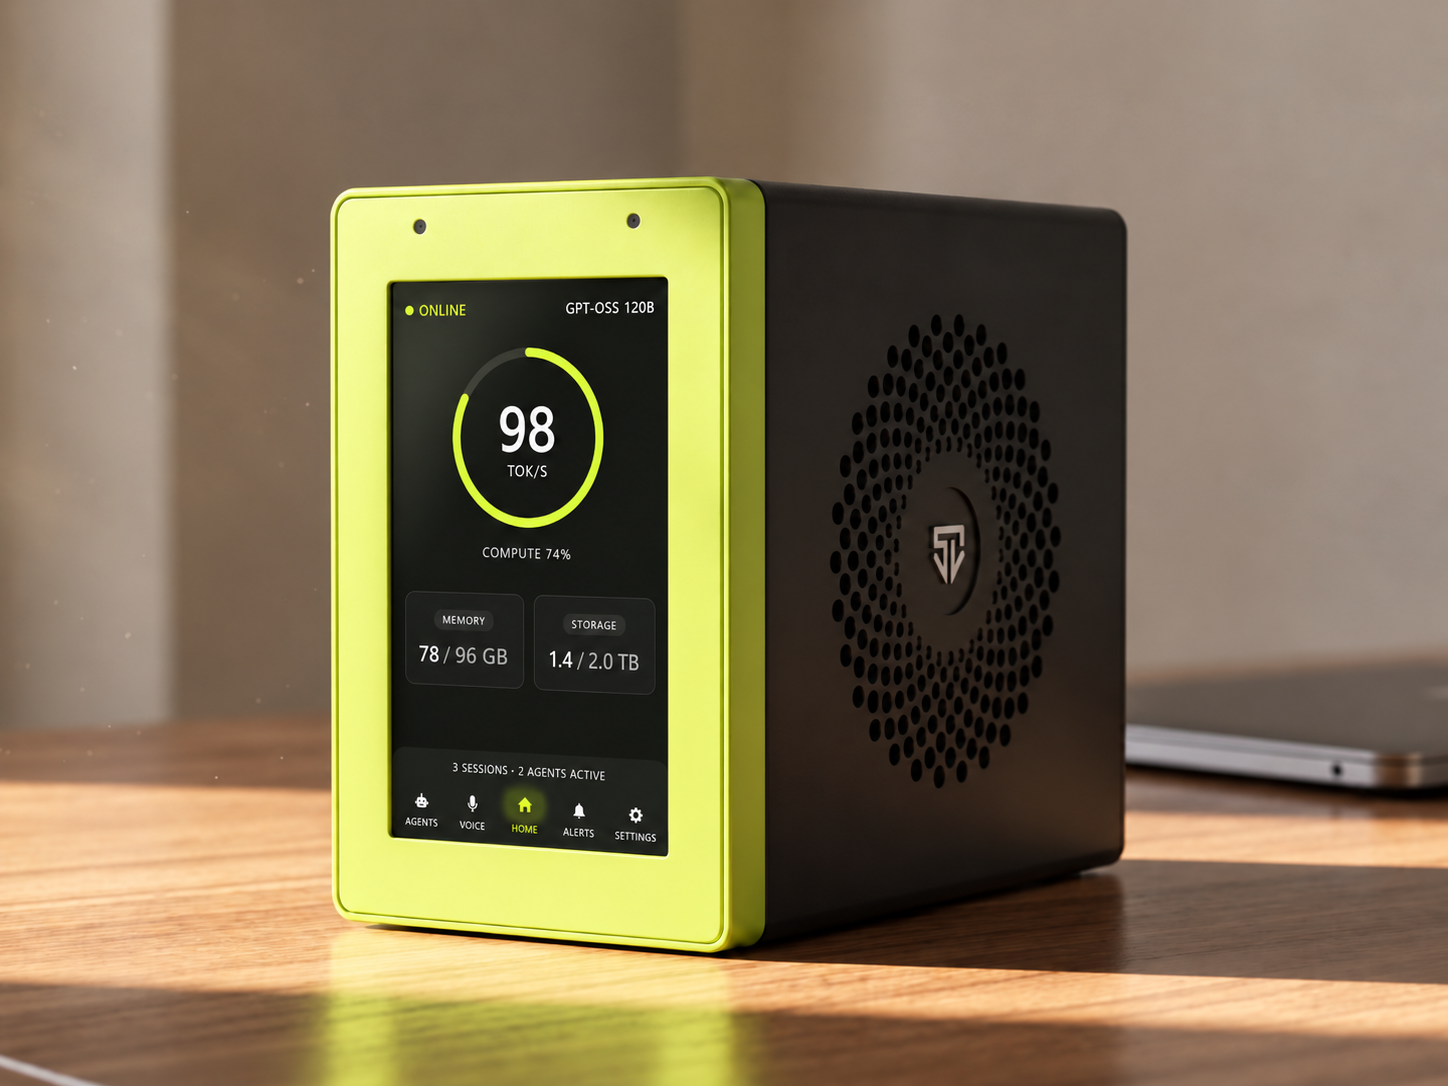
Compact systems powered by the OPU bring datacenter-class AI to robotics, automation, and real-time decision-making. With unified memory and ultra-low latency, they run large models locally without cloud dependence or data movement overhead.
In the Datacenter and Cloud
Multi-processor configurations scale from petaFLOP to exaFLOP performance with linear efficiency. Unified software orchestration and distributed coherence allow seamless transitions between fine-tuning, training, and large-scale inference; accelerating workloads while reducing cost and power by up to 90%.
Related insights
Our architecture provides unmatched computational efficiency, allowing intricate AI models to operate with low latency and high throughput.
Beyond GPUs: why we built Tsavorite
Our view is that AI has outgrown the way the industry builds computers for it. Adding more of the same hardware is no longer the answer. AI needs an architecture designed for it from the start, one that becomes more efficient as it grows rather than less.
Tsavorite Scalable Intelligence Sets New Frontier for AI Efficiency and Scale with the Omni Processing Unit
Transform your AI infrastructure today
Connect with our team of experts to discover how Tsavorite can accelerate your AI development and deployment.
Contact Us