Helix-M
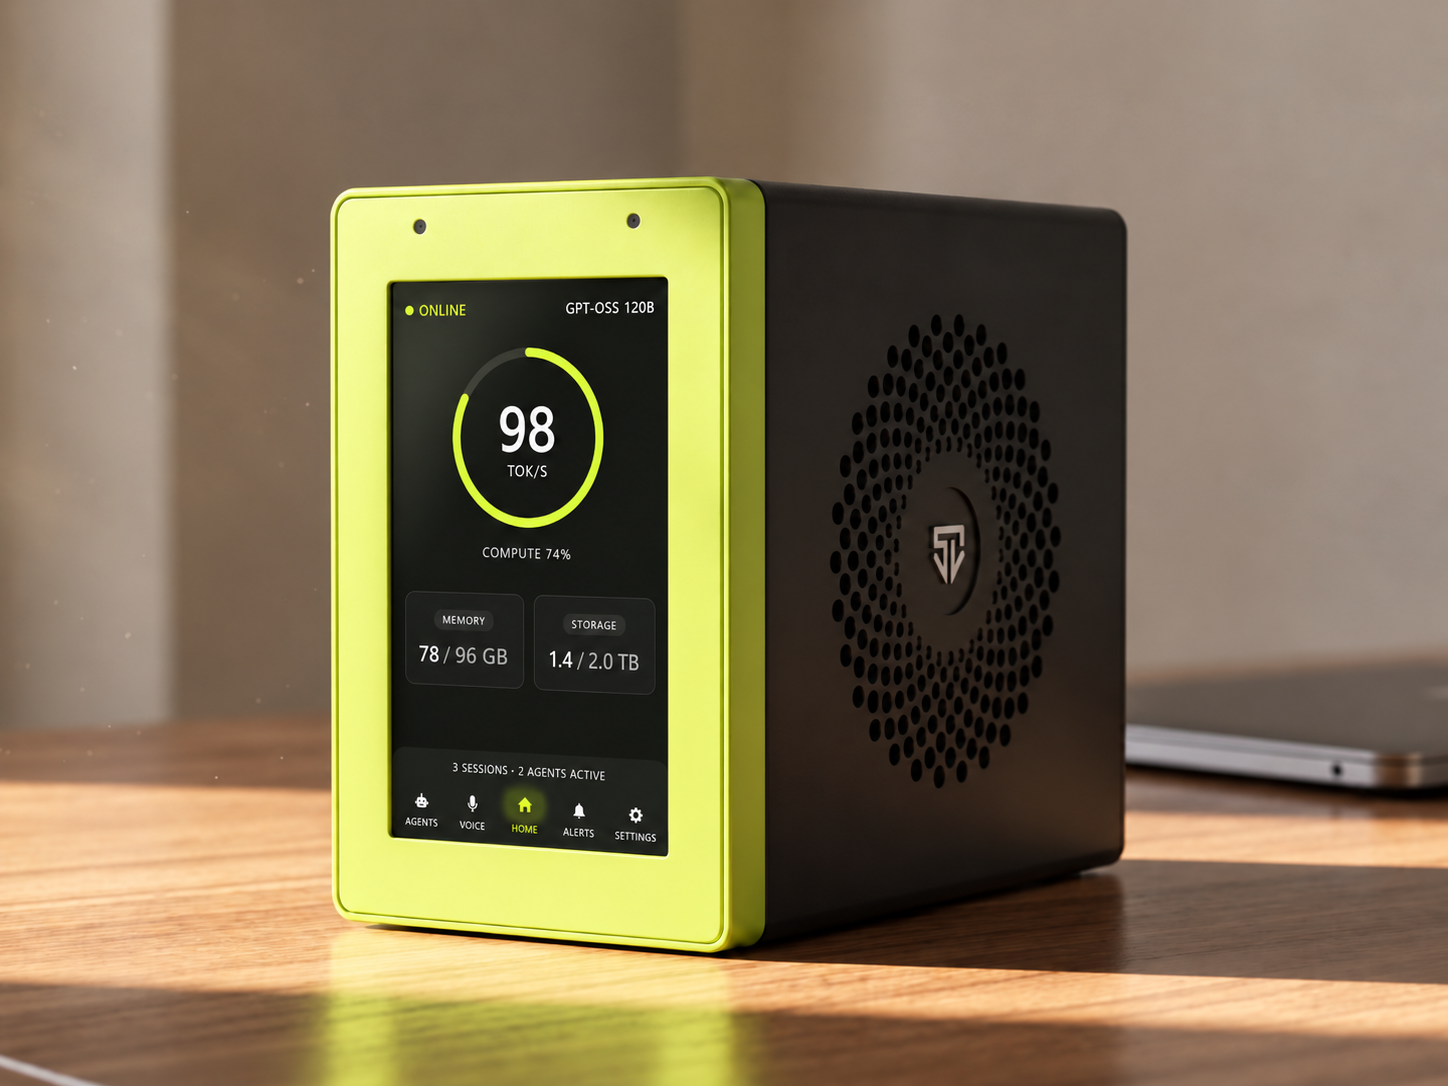
A high-performance AI system that delivers private, low-latency intelligence exactly where it’s needed: on a clinician’s desk, a factory floor, in a legal office, or inside an autonomous device. With the ability to run multimodal models locally and support end-to-end AI workflows, Helix-M enables confidential document processing for law and medicine, real-time perception for robotics and industrial automation, private fine-tuning and inference for developers, and creative on-device AI for field deployments. Powered by the OPU, it delivers PetaFLOP-scale performance while maintaining a compact form factor.
Private AI, Wherever Work Happens
High-performance AI delivering secure, low-latency intelligence without cloud dependency or compromise
On-Device Intelligence
Run multimodal models, inference, and fine-tuning locally for real-time results with full data privacy and deterministic latency

Built for Confidential Workflows
Ideal for healthcare, legal, industrial, and field deployments where data sovereignty and offline operation are non-negotiable.

Extreme Performance, Minimal Footprint
PetaFLOP-class compute in a palm-sized system, powered by the OPU and optimized for power-efficient edge deployment.
PetaFLOP-scale AI in a palm-sized system
Helix-M packs datacenter-class AI into a 3 by 6 inch desktop system. A single Tsavorite OPU delivers 1,500 TOPS with unified high-bandwidth memory, so you can run 100B-parameter models and multimodal agents locally at around 100 tokens per second.
On-device intelligence
Run multimodal models, inference, and fine-tuning entirely on your desk. Every token is processed locally, keeping sensitive data private and delivering deterministic, low-latency results with no cloud round-trips or usage fees.
Unified high-bandwidth memory
Models get a single large, fast memory space. Load multiple models and longer contexts without partitioning across devices or spilling to slower storage.
Efficient by design
The OPU delivers PetaFLOP-class compute in a device quiet enough for a clinician’s desk, a legal office, or a factory floor. No special power, cooling, or networking required.
Datacenter AI, desktop scale
1000
TOPS AI performance
96 GB
Unified memory @ 300GB/s
100 t/s
GPT-OSS 120B
70 W
Power over Ethernet
FAQs
Common questions about Helix-M, its capabilities, and how it fits into your workflow.
What is Helix-M?
Helix-M is a palm-sized personal AI appliance powered by a single Tsavorite OPU. It delivers 1,000 TOPS of AI performance with up to 96GB of unified high-bandwidth memory in a mini form factor. It runs multimodal models, inference, and fine-tuning locally, so you get private, low-latency intelligence on your desk without depending on the cloud.
What models can it run?
Helix-M runs models up to ~100B parameters locally, including large language, vision, and multimodal models. It supports popular runtimes and tooling such as Ollama and llama.cpp, so you can deploy open models and end-to-end AI workflows with minimal setup.
How is my data kept private?
Because every token is processed on-device, your data never leaves the system. There are no cloud round-trips and no third-party inference services in the loop. That makes Helix-M well suited to healthcare, legal, industrial, and other environments where data sovereignty and confidentiality are non-negotiable, and it can operate fully offline.
Where can I deploy it?
Helix-M needs no special power, cooling, or networking. It is an all-inclusive appliance that does not need any additional monitors, keyboard etc and works with existing phone/laptops/desktops etc.
How does it compare to a GPU?
Helix-M delivers PetaFLOP-class performance in a fraction of the power and footprint of a traditional GPU workstation, with a large unified memory space that avoids splitting models across devices. For teams that need more capacity, Helix-D and rack-scale Helix-R scale the same architecture up to larger models and higher throughput.
Related insights
Our architecture provides unmatched computational efficiency, allowing intricate AI models to operate with low latency and high throughput.
Beyond GPUs: why we built Tsavorite
Our view is that AI has outgrown the way the industry builds computers for it. Adding more of the same hardware is no longer the answer. AI needs an architecture designed for it from the start, one that becomes more efficient as it grows rather than less.
Tsavorite Scalable Intelligence Sets New Frontier for AI Efficiency and Scale with the Omni Processing Unit
Bring private AI to your desk
See what Helix-M can do for your team. Talk to us about pilots, availability, and how Helix scales from desktop to rack.
Talk to our team