MultiPlexus
MultiPlexus is the coherent fabric that makes the OPU composable. One fabric spans every scale: a high-performance network on chip with distributed caches, extended over UCIe to connect every chiplet in a package, over SerDes to connect every package in a system, and across systems and racks to form unified memory pods. As the fabric scales up, arithmetic intensity rises as much as 10x and AI compute utilization climbs with it.
One Fabric, Every Scale
From chiplet to rack, MultiPlexus keeps compute coherent and memory unified, so utilization rises as systems scale instead of falling.
Load/store across racks
OmniCores read and write memory anywhere in the domain through simple 128-byte load/stores.

Utilization that scales up
Arithmetic intensity increases up to 10x, and compute utilization grows as the fabric scales.
Speaks your protocols
The fabric transparently tunnels and bridges AMBA/CHI, PCIe, CXL, Ethernet, and more.
The MultiPlexus fabric
The connective tissue of the OPU: a coherent, non-blocking fabric that links chiplets, packages, systems, and racks into one compute domain with unified memory.
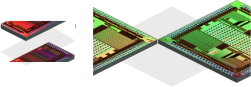
Highest performance, coherent, scalable network on chip with distributed caches
Extends over UCIe; connecting all chiplets in a package
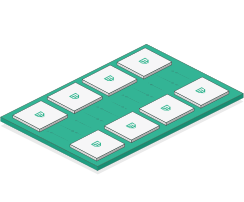
Extends over SERDES; connecting all packages in a system
Scales-up across systems and racks to form unified memory pods
A coherent fabric from chiplet to rack
MultiPlexus delivers PetaByte-scale bandwidth with sub-nanosecond hops and a non-blocking architecture, backed by gigabyte-scale caches. Hardware-synchronized agents connect OmniCores, Neoverse cores, memory, I/O, and security into one automatically routed fabric.
Hardware-defined routing and QoS
Composable agent types, including AI OmniCores, Neoverse cores, fabric caches, memory controllers, I/O controllers, and crypto and security blocks, attach to the fabric and stay hardware-synchronized. Routing and quality of service are automated and defined in hardware, so no software tuning is required.
Unified memory at any scale
MultiPlexus maps global physical addresses across the entire domain, forming PetaByte-scale universal memory that scales to 8K OPUs. AI OmniCores perform 128-byte load/stores across nodes through virtual addresses, so software sees one memory space, not a cluster of machines.
Built for reliability and security
End-to-end ECC protection, transaction-level retry and redundant paths, deliver dependable operation, along with end-to-end security.
Fabric numbers that change the math
PB-scale
fabric bandwidth
8 K
OPUs in one domain
10 x
arithmetic intensity
<1ns
per fabric hop
FAQs
Common questions about MultiPlexus, how it scales, and how it compares to conventional interconnects.
What is MultiPlexus?
MultiPlexus is the coherent fabric at the heart of Tsavorite’s architecture. It begins as a high-performance, coherent network on chip with distributed caches, extends over UCIe to connect all chiplets in a package, extends over SerDes to connect all packages in a system, and scales up across systems and racks to form unified memory pods. The same fabric operates at every one of those scales.
How is it different from a network?
Conventional clusters move data through packet networks, with software stacks, NICs, and synchronization overhead at every hop. MultiPlexus uses load/store semantics instead: sub-nanosecond hops, a non-blocking architecture, and hardware coherency mean compute simply reads and writes memory, wherever it lives. Software sees one machine with one memory space rather than a cluster of nodes exchanging messages.
How large can it scale?
MultiPlexus maps global physical addresses across the whole domain and scales up to 8K Omni Processing Units, forming PetaByte-scale universal memory. AI OmniCores perform 128-byte load/stores across nodes through virtual addresses, and because arithmetic intensity increases as the fabric grows, compute utilization rises with scale rather than degrading.
How does it stay reliable at scale?
Reliability is engineered into the fabric: end-to-end ECC protection, transaction-level retry, and redundant paths keep traffic flowing through faults, while advanced design-for-test supports manufacturing quality. Routing and quality of service are automated and hardware-defined through synchronized agents, so behavior stays predictable as domains grow to thousands of OPUs.
Related insights
Our architecture provides unmatched computational efficiency, allowing intricate AI models to operate with low latency and high throughput.
Beyond GPUs: why we built Tsavorite
Our view is that AI has outgrown the way the industry builds computers for it. Adding more of the same hardware is no longer the answer. AI needs an architecture designed for it from the start, one that becomes more efficient as it grows rather than less.
Tsavorite Scalable Intelligence Sets New Frontier for AI Efficiency and Scale with the Omni Processing Unit
See what one compute domain can do
Talk to us about MultiPlexus, the OPU, and how a coherent scale-up fabric changes your system architecture.
Talk to our team