Helix-D
A desktop-class, high-performance AI system designed for developers, enterprises, and advanced edge deployments that need datacenter-grade capability without datacenter complexity. Housed in a compact workstation form factor, Helix-D delivers massive local compute, unified memory, and low-latency execution for full end-to-end AI workflows; from model development and fine-tuning to real-time multimodal inference. Powered by one or more OPUs, it enables teams to run large language models, vision and video pipelines, agentic workflows, and private RAG systems entirely on-prem or at the edge.
Datacenter-Class AI on your Desktop
A powerful AI system for developers, teams, and enterprises building, running, and scaling advanced AI locally.
Full-Stack AI Workflows
Develop, fine-tune, and deploy large models end-to-end without relying on or paying for shared cloud infrastructure
Enterprise-Ready, On-Prem
Deliver predictable performance, data control, and low latency for regulated or IP-sensitive enterprise environments

Scale-Up When You’re Ready
Link multiple Helix-D systems via MultiPlexus to form a coherent compute domain as workloads and teams grow
Datacenter-class AI in a workstation
Helix-D pairs Tsavorite OPUs with 192GB of unified memory. Develop, fine-tune, and serve large models end-to-end at thousands of tokens per second, from a compact desktop system that runs on standard office power.
Full-stack AI workflows
Take models from development and fine-tuning to real-time multimodal inference on a single system. Run large language models, vision and video pipelines, agentic workflows, and private RAG entirely on-prem, without renting shared cloud GPUs.

Massive unified memory
192GB of memory at 600GB/s lets you load large models and long contexts in one coherent space. OPUs are linked over a 500GB/s any-to-any fabric, so compute and memory scale together without partitioning overhead.
Scale up when you’re ready
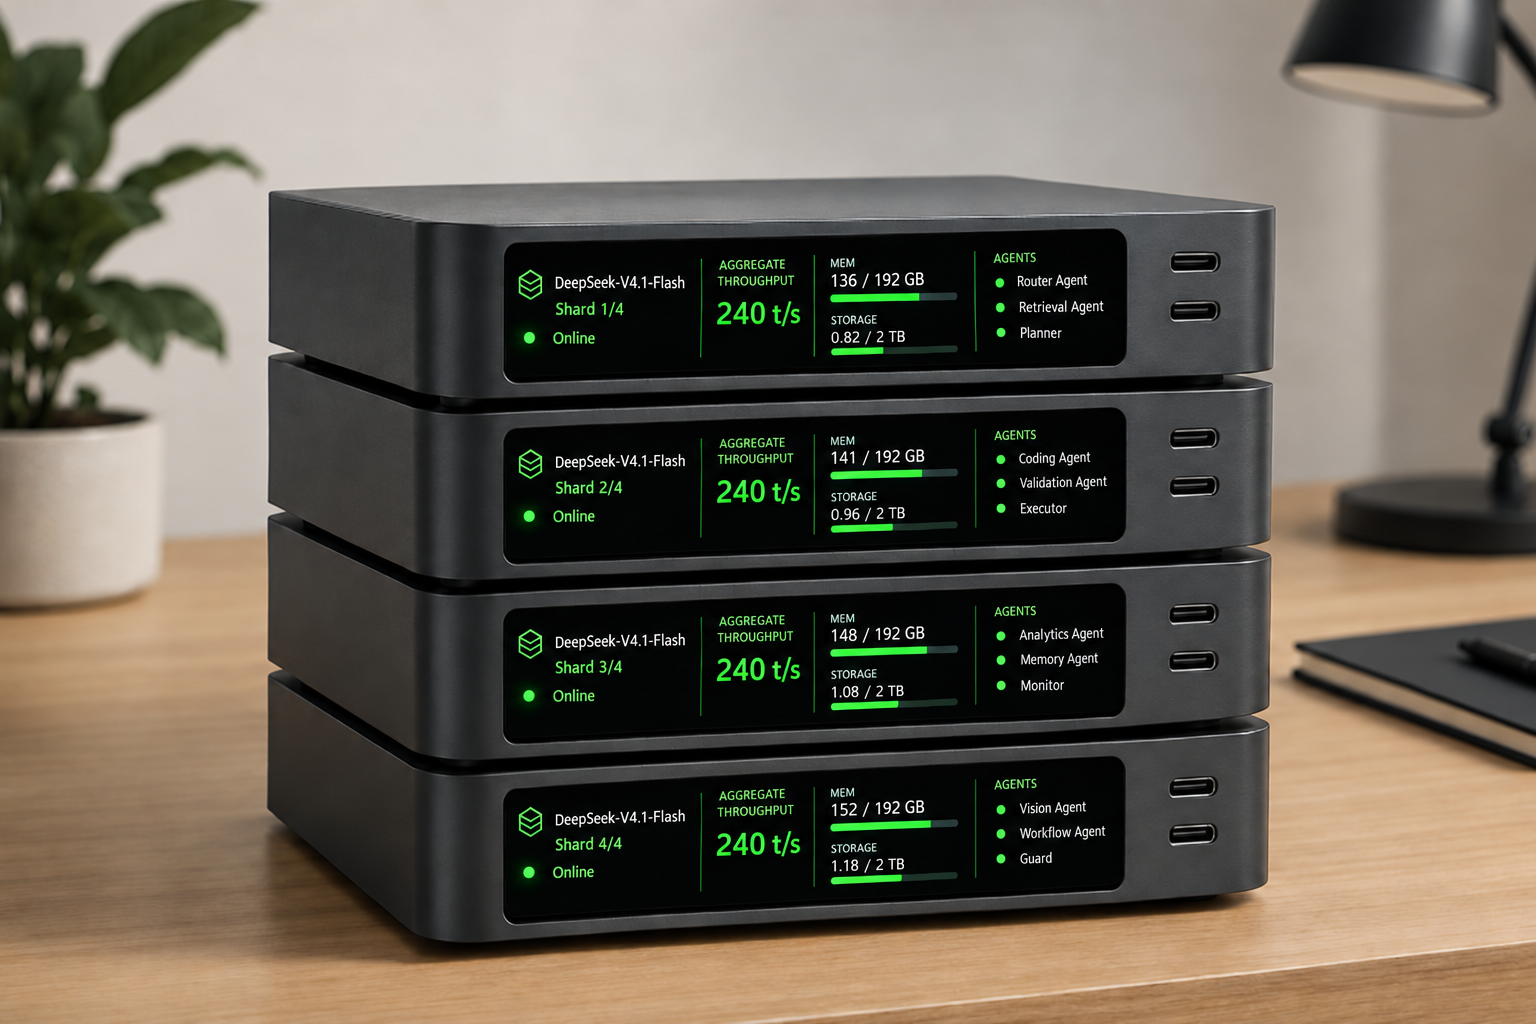
Stack up to four Helix-D systems into one coherent domain for 8 PetaFLOPS and 768GB of memory, enough to run trillion-parameter models with datacenter-class performance. High-speed 100GbE and PCIe 7.0 keep everything in sync.
Built to run the largest models on your desk
8000
TOPS AI performance
768 GB
unified memory @ 600GB/s
240 t/s
DeepSeek-V4.1-Flash
FAQs
Common questions about Helix-D, its performance, and how it fits into your development and deployment workflows.
What is Helix-D?
Helix-D is a desktop-class AI workstation powered by two Tsavorite OPUs. Each unit delivers 2 PFLOPS of AI performance with 192GB of unified high-bandwidth memory in a compact 180W system. Built for developers, teams, and enterprises, it runs full end-to-end AI workflows, from model development and fine-tuning to real-time multimodal inference, entirely on-prem or at the edge.
What models can it run?
With 192GB of unified memory, Helix-D runs large language models, vision and video pipelines, agentic workflows, and private RAG systems natively at thousands of tokens per second. Stack up to four Helix-D systems together to reach 768GB of memory and run trillion-parameter models with datacenter-class performance.
How does it scale?
A single Helix-D is a complete AI workstation. When you need more, link multiple systems through Tsavorite’s MultiPlexus fabric to form one coherent compute domain. Four stacked systems deliver 8 PFLOPS and 768GB of memory, so capacity grows with your workloads and teams without re-architecting.
Why on-prem instead of cloud?
Running locally gives you predictable performance, full control of your data, and low latency, which matters for regulated or IP-sensitive environments. There are no per-hour GPU rentals or shared-infrastructure queues. You own the system and the economics, with Tsavorite delivering substantially lower cost per token than comparable GPU platforms.
How does it compare to a GPU workstation?
Helix-D delivers datacenter-class throughput in a fraction of the power and footprint of a traditional multi-GPU workstation, with a large unified memory space that avoids splitting models across cards. For smaller deployments, Helix-M brings the same architecture to a palm-sized appliance; for rack-scale needs, Helix-R scales up to full edge-datacenter performance.
Related insights
Our architecture provides unmatched computational efficiency, allowing intricate AI models to operate with low latency and high throughput.
Beyond GPUs: why we built Tsavorite
Our view is that AI has outgrown the way the industry builds computers for it. Adding more of the same hardware is no longer the answer. AI needs an architecture designed for it from the start, one that becomes more efficient as it grows rather than less.
Tsavorite Scalable Intelligence Sets New Frontier for AI Efficiency and Scale with the Omni Processing Unit
Run the largest models on your terms
See how Helix-D brings datacenter-class AI to your team. Talk to us about pilots, availability, and scaling from desktop to rack.
Talk to our team