Helix-R
A rack mountable, scale-up ready, high-performance AI platform that links systems through the MultiPlexus fabric into one coherent compute domain. It deploys seamlessly in existing infrastructure, scaling from edge clusters to exascale networks with linear efficiency gains. Powered by multiple OPUs, Helix-R redefines what’s possible at the edge.
One Fabric. One Compute Domain.
A rack-mountable, scale-up AI platform that unifies multiple Helix-R AI systems through the MultiPlexus fabric into a single high performance system
True Scale-Up Architecture
Connect OPUs across systems with load/store semantics, enabling low-hop, low-latency scaling without traditional bottlenecks.

Metro-Scale AI at the Network Edge
A rack-mountable AI platform built for metro and telco environments, delivering low-latency, scale-up intelligence directly inside the network
Fits Where You Deploy
Seamlessly integrates into existing datacenter and edge infrastructure without specialized networking or re-architecture.
One fabric. One coherent compute domain.
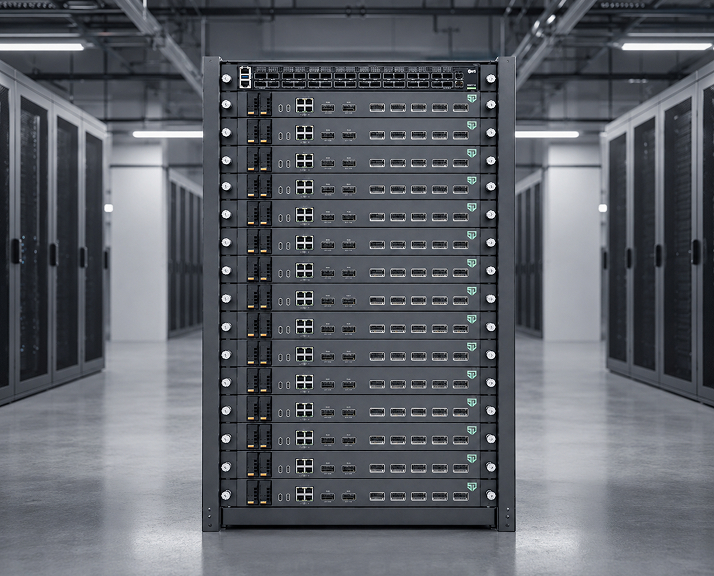
Helix-R links multiple rack-mounted nodes through the MultiPlexus fabric into a single scale-up system with load/store semantics. Each 1RU node delivers 5 PFLOPS and 480GB of memory.
True scale-up architecture
Connect OPUs across nodes with native load/store semantics for low-hop, low-latency scaling. MultiPlexus removes the bottlenecks of existing fabrics, so a cluster of up to 18 systems behaves like one large machine rather than many small ones.
Metro-scale AI at the network edge
Purpose-built for metro and telco environments, Helix-R brings scale-up intelligence directly inside the network. A single node runs trillion-parameter models and can scale to multiple nodes based on power and performance requirements.
Fits where you deploy
Each node is a thin 1RU chassis, 19 inches wide and under 17 inches deep, air-cooled and standard-rack ready. Helix-R drops into existing datacenter and edge infrastructure with 400GbE connectivity, no specialized networking or re-architecture required.
All the performance at half the power
92
PFLOPS per rack
8.6 TB
Unified memory
27 TB/s
Memory bandwidth
12.6 KW
Total power
FAQs
Common questions about Helix-R, its scale-up architecture, and how it deploys in datacenter and edge environments.
What is Helix-R?
Helix-R is a rack-mountable, scale-up AI platform for edge and datacenter deployment. Each thin 1RU node is powered by multiple Tsavorite OPUs, delivering 5 PFLOPS and 480GB of memory at 1.5TB/s. Up to 18 nodes link through the MultiPlexus fabric into one coherent compute domain to serve frontier-scale workloads.
How does it scale up?
Helix-R uses the MultiPlexus fabric to connect OPUs across nodes with native load/store semantics and 1.2TB/s bidirectional bandwidth. This low-hop, low-latency design lets a cluster behave like one large machine. A 13KW configuration can serve DeepSeek-V4.1-Flash with 1M context at 500 tokens per second per user.
Where does Helix-R deploy?
Helix-R is designed for metro, telco, and edge-datacenter environments. Each node is 19 inches wide, under 17 inches deep, air-cooled, and standard-rack ready, with 400GbE connectivity. It integrates into existing infrastructure without specialized networking or re-architecture, bringing scale-up intelligence directly inside the network.
Related insights
Our architecture provides unmatched computational efficiency, allowing intricate AI models to operate with low latency and high throughput.
Beyond GPUs: why we built Tsavorite
Our view is that AI has outgrown the way the industry builds computers for it. Adding more of the same hardware is no longer the answer. AI needs an architecture designed for it from the start, one that becomes more efficient as it grows rather than less.
Tsavorite Scalable Intelligence Sets New Frontier for AI Efficiency and Scale with the Omni Processing Unit
Scale AI at the edge
See how Helix-R delivers rack-scale AI at a fraction of the power and cost. Talk to us about pilots, availability, and deployment.
Talk to our team